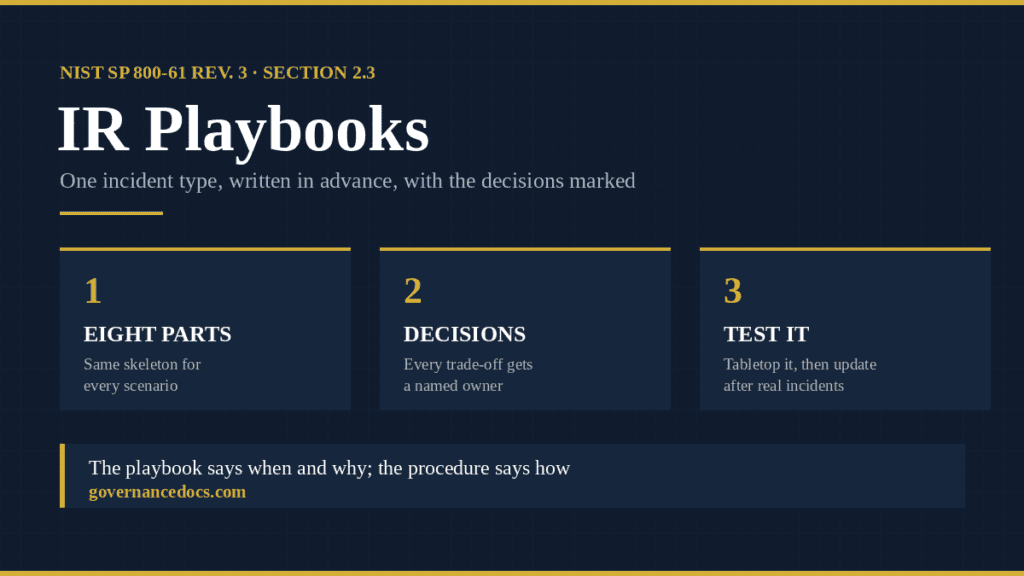
An incident response playbook is a set of actionable steps for one type of incident, written in advance so the people on shift do not have to invent the response while it is happening. NIST SP 800-61 Rev. 3 expects you to have them. It names playbooks alongside policies and procedures as part of a working incident response capability.
This post covers what an incident response playbook is and is not, the structure we recommend, which scenarios deserve one first, and the mistakes that turn playbooks into shelfware.
Why Rev. 3 asks for an incident response playbook
Rev. 3 is a CSF 2.0 Community Profile, and it says outright that the details of how to perform incident response change too often to capture in one static publication (our NIST 800-61 Rev 3 overview explains the change). That pushes the “how” down into your own documents.
Section 2.3 describes three kinds of operational document that sit under the policy:
Playbooks that give actionable steps to follow for particular scenarios.
Procedures for the most common incident types.
Procedures for urgent processes, with NIST’s example of redeploying the primary authentication platform.
Rev. 3 points to CISA’s Cybersecurity Incident & Vulnerability Response Playbooks (2021) as examples. They are a useful reference for the level of detail a playbook can carry. Write your own, though: your systems, your contacts and your decision rights are what make an incident response playbook usable.
Playbook vs procedure vs plan
The terms blur, so fix them in your documentation hierarchy. Our incident response policy post covers the policy layer in detail. The short version:
Document
Answers
Scope
Changes when
Policy
What we commit to, and who has authority
Whole organization
Leadership or obligations change
Plan
How the capability is organized and resourced
Whole program
Structure, contacts or services change
Incident response playbook
What to do for this scenario, in what order, and where the decisions are
One incident type
The threat, your tools or lessons learned change
Procedure
Exactly how to perform one task
One task or system
The system changes
A useful test: if a step reads “isolate the host using the EDR console,” the click-by-click detail belongs in a procedure that the incident response playbook links to. The playbook says when and why. The procedure says how.
A standard incident response playbook structure
Use the same skeleton for every scenario. Responders learn where to look once, and gaps show up when a section is empty. This structure is our recommendation; the right column shows the Rev. 3 outcome each section supports.
Section
What it contains
Rev. 3 anchor
1. Scope and triggers
The incident type covered, and the alerts or reports that should open this playbook
DE.AE-08, RS.MA-03.R1
2. Declaration and initial severity
Criteria for declaring an incident; which risk factors to score first for this type
DE.AE-08.R1, RS.MA-02.R1
3. Roles
Incident lead, required participants, specialist teams, third parties to call
RS.MA-01.C1, RS.MA-01.R2
4. Investigation
Questions to answer, data sources to pull, how to scope other potential targets
RS.AN-03, RS.AN-08
5. Containment and eradication
Options with their business impact, duration and who may authorize each
RS.MI-01, RS.MI-02
6. Decision points
The trade-offs this scenario forces, and who decides
RS.MA-03.R3
7. Communication
Internal updates, notification checks, media handling
Rev. 3’s RS.MI note suggests evaluating each containment measure by how long it will stay in place: an emergency workaround removed within hours, a temporary workaround removed within two weeks, or a permanent fix. An incident response playbook that lists “block the IP” without saying who removes the block, and when, leaves debris behind.
Decision points need owners
RS.MA-03.R3 asks you to balance quick recovery against observing the attacker or investigating more thoroughly. Every scenario has a version of that trade-off. Write it down, name who makes the call, and list the facts they will need. RS.MI R1 adds that redirecting an attacker to a sandbox delays containment and should be discussed with legal first.
Evidence is not optional
RS.AN-06 and RS.AN-07 ask you to record actions taken and preserve the integrity and provenance of incident data. Each playbook should say what to capture before containment destroys it, and where to store it.
Which incident response playbook to write first
Rev. 3’s RS.MA-03.R1 gives four example incident types: data breach, ransomware, account takeover and denial of service. Those are a sensible floor. Beyond them, choose by your own risk assessment (ID.RA), not by the news cycle. The scenarios below are the ones we would cover first:
Scenario
Why it needs its own playbook
Ransomware
Availability, backups and a payment decision all arrive at once
Data breach or exfiltration
Notification analysis starts early and depends on the data involved
Account takeover
Containment runs through the identity provider, not the network
Business email compromise
Finance and payment processes are part of containment
Denial of service
Containment may depend on your internet or cloud service provider
Cloud service compromise
Shared responsibility shapes who can see and act on what
Supplier or software supply chain compromise
You may learn about it from the supplier, on their timetable
Insider threat
HR and legal lead parts of the response
Web application compromise
Customer-facing impact, and the fix may be a code change
Lost or stolen device
Simple, and easy to handle inconsistently without a script
Rev. 3 also calls out procedures for urgent processes. Redeploying your primary authentication platform is the example it gives. If an attacker owns your identity provider, every other incident response playbook stalls, so write that procedure early.
Example: the first page of an account takeover playbook
Here is what the first page of an incident response playbook can look like for account takeover. It is an outline, not a finished document, and the details will depend on your identity provider and your logging.
Triggers. Impossible-travel or anomalous sign-in alerts, a user reporting a password reset they did not request, new mailbox forwarding rules, or a multifactor prompt the user did not initiate.
Declare if. A sign-in succeeded that the user cannot account for, or account settings changed without the user’s action. Apply your known false positives first, as DE.AE-08.R1 asks.
Score first. Asset criticality (what the account can reach) and stage of activity (has it been used to reach anything else).
First actions. Revoke active sessions, reset the credential, review and re-register multifactor methods, and preserve the sign-in and audit logs before anything rotates out.
Decision point. If the account is privileged, the incident lead decides whether to treat the identity platform itself as compromised and move to the urgent-process procedure.
Look wider. Search for the same source addresses, devices and techniques against other accounts, so the scope is not limited to the first victim (RS.AN-08.R1).
Everything after this page (investigation detail, communication templates, recovery checks) can be longer. The first page is what a responder reads under pressure.
Keeping an incident response playbook alive
A playbook written once and never tested can end up describing tools you no longer run and people who have left. Rev. 3’s improvement outcomes cover this. ID.IM-02 asks for improvements identified from tests and exercises, and refers to NIST SP 800-84 for tabletop discussions and simulations. ID.IM-04 R2 asks you to review plans periodically or when significant improvements are needed.
Exercise each incident response playbook in a tabletop at least once in its review cycle.
Update it after every real incident of that type, as part of the after-action report.
Give each playbook a named owner and a version history.
Check every contact and link when you review. A dead phone number in a playbook is a finding.
Common incident response playbook mistakes
Too long to use. If the first action is on page nine, responders will skip it. Put the first actions on the first page.
No decision rights. “Consider isolating the server” is not a step. Say who decides and on what evidence. Our incident response roles and responsibilities post covers how to assign that authority.
Copied, not adapted. A downloaded playbook that names systems you do not have will be ignored at the first sign of trouble.
No exit criteria. Without criteria for ending recovery, an incident can stay open indefinitely and the after-action report never gets written.
Incident response playbook FAQ
Does NIST SP 800-61 Rev. 3 include playbook templates?
No. NIST SP 800-61 Rev. 3 recommends playbooks and points to CISA’s 2021 playbooks as examples, but it does not supply templates.
How many playbooks do we need?
Start with the incident types your risk assessment ranks highest, then add more as exercises and real incidents expose gaps. Coverage of your top risks matters more than a high count.
Should an incident response playbook be automated?
Parts of it can be. Rev. 3 considers automated containment and eradication, but also asks that handlers can still choose and perform actions manually.
How long should an incident response playbook be?
Short enough that the first actions fit on one page, with detail pushed into linked procedures.
Our Incident Response Toolkit provides 93 editable templates aligned to NIST SP 800-61 Rev. 3 — including the Playbook Framework and Blank Playbook and 13 scenario playbooks, from the Ransomware Playbook onward — for $99.